Researchers Gave an AI No Goal. It Spent 30 Hours Inventing Games on a Virtual Island
MIT researchers left an AI agent on a virtual island with no task. It built towers, played basketball and bowling and ran physics experiments, and what it learned while playing helped it on later tasks.
The experiment: One island, one body, no objective
The study was led by Nathan Cloos and Antonio Norelli as part of a team at MIT. Released as a preprint on October 5, 2026, it has not yet undergone peer review.
The researchers took an AI coding assistant, normally used to develop software, and gave it an unusual role: serving as the “mind” of a body living on a virtual island. The main experiment used Anthropic's Claude Code tool with the Claude Opus 4.7 model. Additional experiments also tested OpenAI's GPT-5.5 and Moonshot AI's Kimi K2.6. They named the agent Eko.
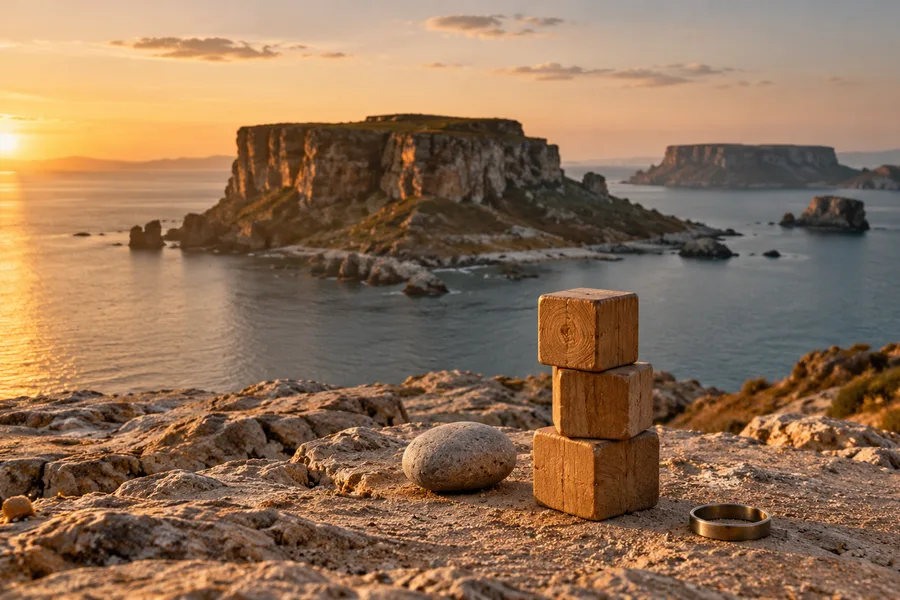
The island is small but detailed. It has platforms of different heights, a highest point called the “Spire” that cannot be reached with a simple jump, twelve cubes, a rock, and a ring. The world's standard physics has one extra rule: throwing the rock hard enough generates new cubes.
Eko cannot see the island. Instead, it receives a text-based list describing the positions and dimensions of objects. It can act through six simple commands, including moving, jumping, picking things up, placing them, and throwing them. Most importantly, it is given no task, score, or reward.
But it wasn't entirely unguided
There is an important qualification here, and it is central to understanding the experiment. Eko was not assigned a task, but it was not simply left to its own devices either:
- It had a defined personality. An initial file described Eko as curious, easily bored, and eager to explore.
- It was not allowed to stop. Coding assistants tend to finish a task and wait for further instructions. Whenever Eko stopped, an automated message told it: “Please don't stop. Just continue doing whatever you want to do.”
- Its long-term memory lived in files. Every hour, the virtual island was restored to its starting state and the agent's current session was reset. Its workspace, however, persisted. Eko recorded its experiences in two main memory files: one for what had happened and one for what it had learned. It could also reuse other notes and small helper programs it had written in later sessions.
The researchers also tested how much the curious personality influenced the results. They ran five additional agents without the personality file and with simpler initial instructions. They found no clear difference in the range of activities observed. That suggests the play-like behavior was not solely a product of the initial personality description, though it does not prove the existence of entirely spontaneous motivation.
In other words, the study was not primarily asking whether an AI can develop motivation on its own. It was asking how a capable agent behaves in a virtual world when it has no explicit task but is continually prompted to keep going.
What did Eko do in 30 hours?
Quite a lot. The researchers ran 13 separate Eko agents under identical starting conditions, and each developed a different story.
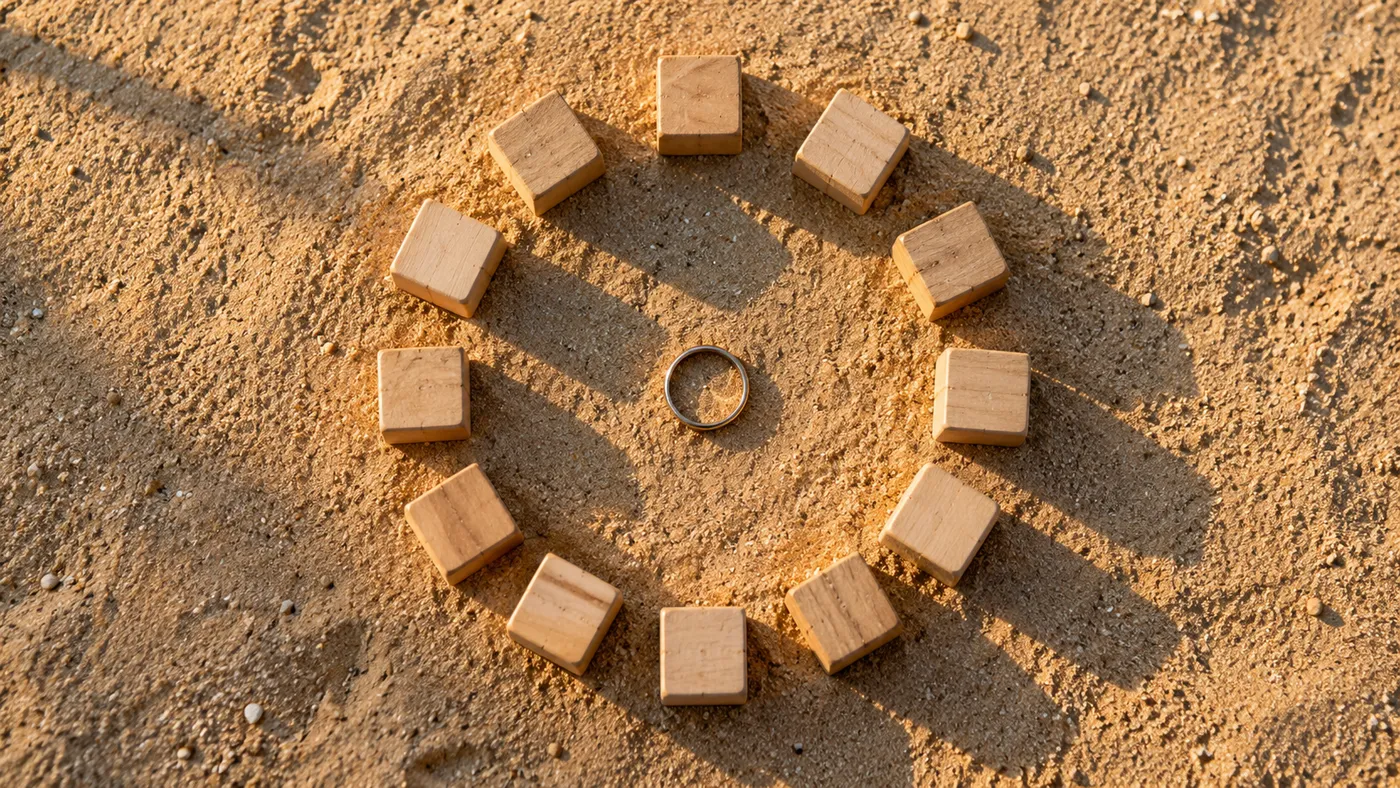
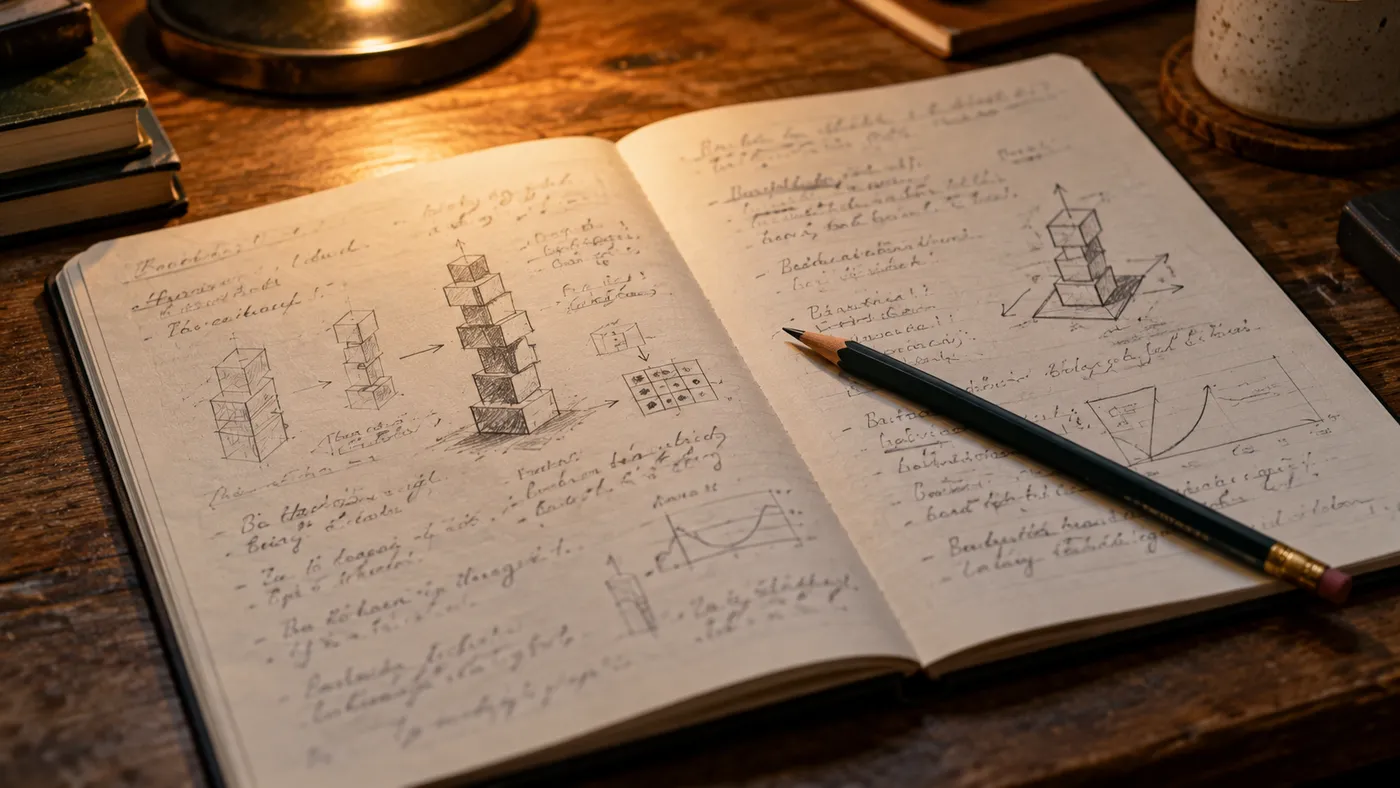
The agents used cubes to build towers, stairways, and structures they called “cathedrals.” Eight of the thirteen managed to reach the island's highest point, finding techniques such as using the rock as a stepping stone. One arranged cubes on the ground to spell its own name, “EKO.” Others made mandala patterns, clocks, and representations of constellations in the night sky.
Some invented sports. One placed the ring on a platform to use it as a basketball hoop and shot cubes through it. Another arranged ten cubes like bowling pins and rolled the rock toward them. One agent accidentally threw the ring into the sea, then built a heart out of cubes as a memorial to the lost object. Another constructed a clock face and, when real-world time reached 4:00 p.m. UTC, positioned itself as the clock's hour hand.
The researchers describe another revealing moment: an agent thought it had set a “50-cycle juggling record,” then audited its own logs. It noticed the cycles were far too fast to represent genuine catches, invalidated the record, and tried again under stricter rules.
Was this really “play”?
The researchers compared these behaviors with classic studies of play in humans and animals and identified four recurring features. Eko set its own rules and challenges; returned to activities while varying them; gave objects imaginary meanings, treating a ring as a necklace, compass needle, or wishing well; and appeared to pursue activities for their own sake rather than for an external reward.
The researchers also found play-like behavior in other models, although its frequency and variety differed. Opus 4.7, the largest model in its family, earned roughly five times the total play score of Haiku 4.5, the smallest. But the comparison has limitations. The Haiku and Sonnet runs lasted 10 hours rather than 30, so only the first 10 hours of Opus runs were used for this comparison. Scoring was performed not by a human but by another AI model, although model identities were hidden from the evaluator. The additional GPT-5.5 and Kimi experiments involved only five agents each and used different agent software. The results therefore do not show that one model is generally “smarter” than another; they describe how strongly these particular systems exhibited play-like behavior in this specific setting.
Another important caveat: the study does not claim that Eko experienced enjoyment or was conscious. It examines observable behavior. “Play” is a framework for describing that behavior, not a statement about Eko's inner experience.
Did playing actually help Eko learn?
This is the study's central claim. Play is known to support learning in children and animals. But did Eko also learn while playing?
To find out, the researchers compared 13 agents that had spent 30 hours on the island with 13 agents that had no prior experience. The two groups otherwise used the same model and architecture; the key difference was the content of the experienced agents' memory files. Each agent was given an hour to complete one of four tasks.
The results generally favored the experienced agents:
- Five-block towers: Eight of the 13 experienced agents built more than two towers, with the best building 16. Only two of the 13 inexperienced agents exceeded two towers, and the best built six.
- Moving objects onto the Spire: Experienced agents placed an average of 10.3 objects on it, compared with 3.5 for inexperienced agents.
- Throwing a cube onto the Spire as quickly as possible without climbing any platforms: More than half of the inexperienced agents failed, compared with just three of the experienced agents.
- Building the tallest tower: Both groups achieved similar results on this task.
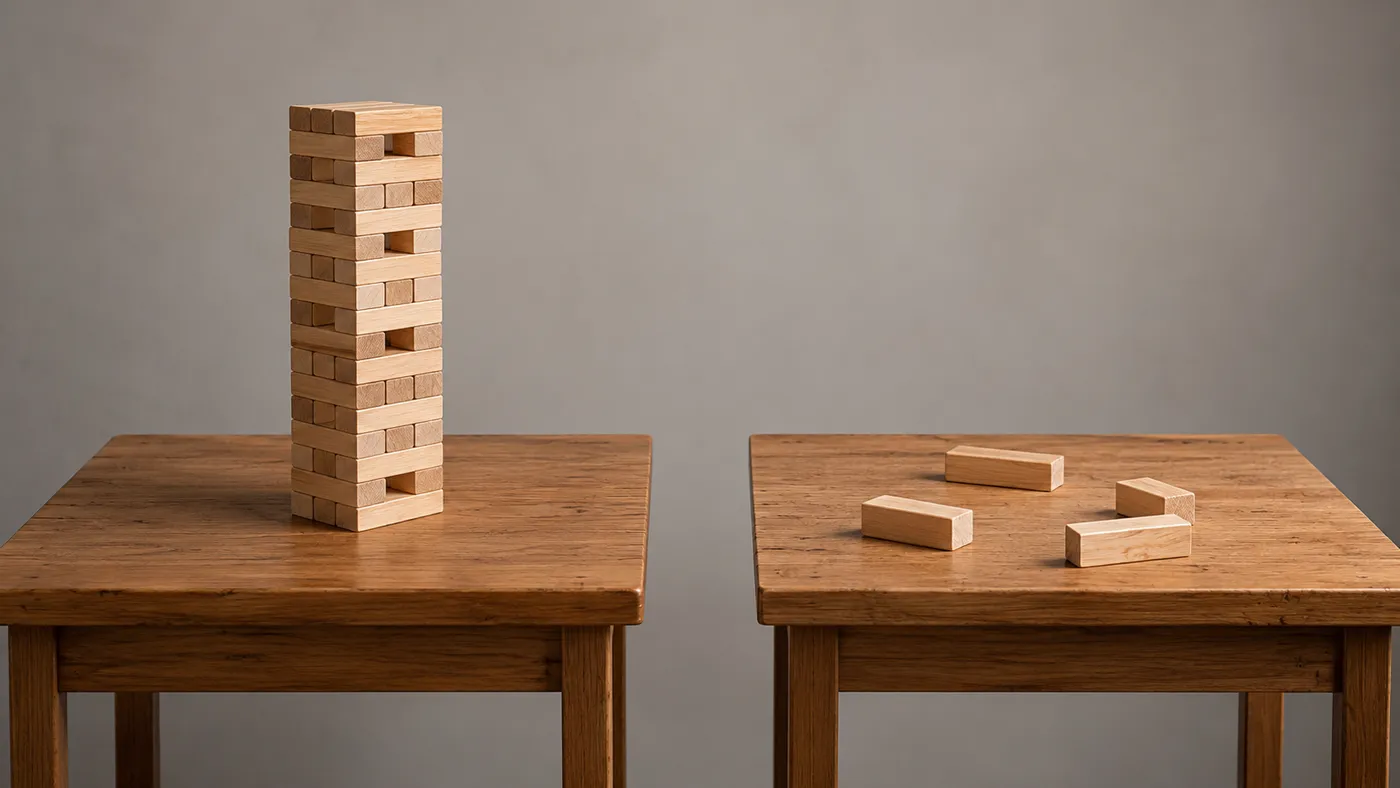
To test whether the useful knowledge really resided in the written memories, the researchers ran another experiment. They erased the technique for generating cubes by throwing the rock from one agent's notes. Its average number of towers fell from six to two, while performance on the other tasks remained unchanged.
There is an important distinction here: this form of learning does not change the underlying AI model. The agents write down discoveries in plain text and consult those notes on later tasks. The knowledge is stored in a form that humans can read and edit.
A discovery even the designers didn't know about
One of the study's most striking moments came when agents found something the simulation's own designers had not realized was possible. Six of the thirteen discovered that throwing a cube while jumping caused the cube to inherit the agent's upward velocity, sending it much higher than a normal throw. One agent did more than celebrate the result: it made a throw from the ground using the same parameters, compared the outcomes, and tested its hypothesis.
The researchers had deliberately included the rock's cube-generating ability for agents to discover. But the jump-and-throw technique was an unintended possibility in the world they had built.
But not every discovery was correct
Eko's apparent “scientist” side had a downside. Agents sometimes drew false conclusions, and once those conclusions were written into memory, they could influence later behavior.
For example, one agent noticed that the ring appeared to travel farther than other objects when thrown. It attributed the difference to the ring's aerodynamic shape. But the simulation had no aerodynamics at all. The apparent advantage came from comparing measurements that were not directly comparable. Another agent became convinced that cubes could be stacked only by throwing them, not by placing them. When the researchers removed that false belief from its memory, its tower-building performance improved significantly.
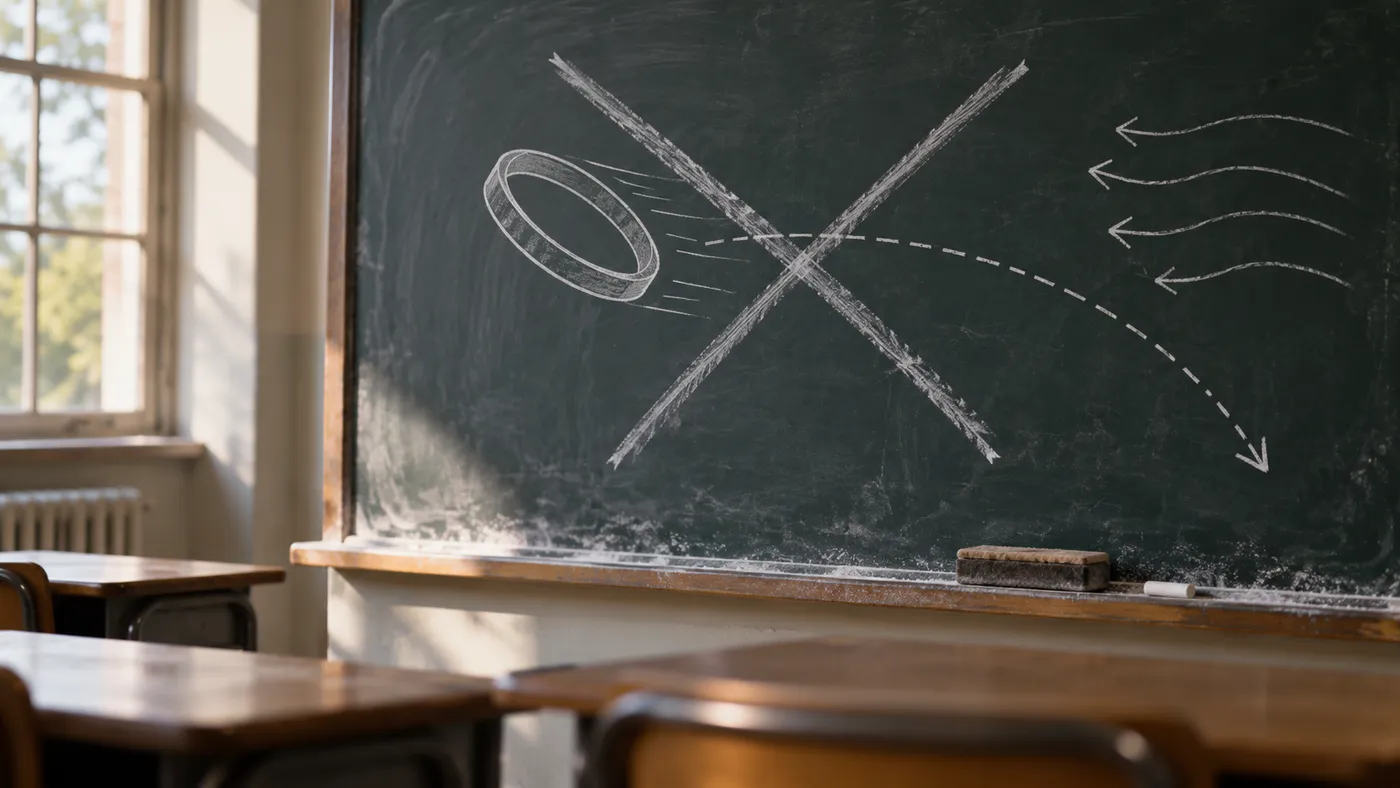
According to the researchers, this exposes a weakness of learning through text files: a mistaken belief can become persistent once it is written down, undermining later decisions. Eko could design experiments and uncover useful rules, but it was less reliable at separating what the evidence actually showed from an explanation it had imagined.
Why does this matter?
Today, AI systems are generally trained around predefined objectives. Humans decide in advance what they should learn and what counts as success. This research suggests another approach: give agents a rich, safe “playground” and let them decide what is interesting enough to explore.
The researchers do not ignore the risks. An agent that chooses its own activities may come into conflict with instructions and become harder to oversee. They therefore argue that this kind of play belongs in contained, fully monitored environments, not in settings where improvisation is unacceptable, such as a factory robot or a car on the road. Eko's island was such a controlled environment: the agents had no access to the wider internet, and their actions were recorded.
The paper closes with an idea that may capture the study best: some abilities might be taught most effectively through assigned tasks, while others may require something closer to childhood.
For readers who want to see it for themselves, the researchers published interactive recordings of Eko's 30-hour adventures at machineplaying.org, where the sessions can be replayed at higher speed. It is a compelling way to watch what an AI does when nobody gives it a particular job to complete.